
AI application security is increasingly about the system around the model. OWASP’s current GenAI guidance includes prompt injection and excessive agency among the risks teams should consider when designing and testing AI applications. OWASP GenAI Security Project.
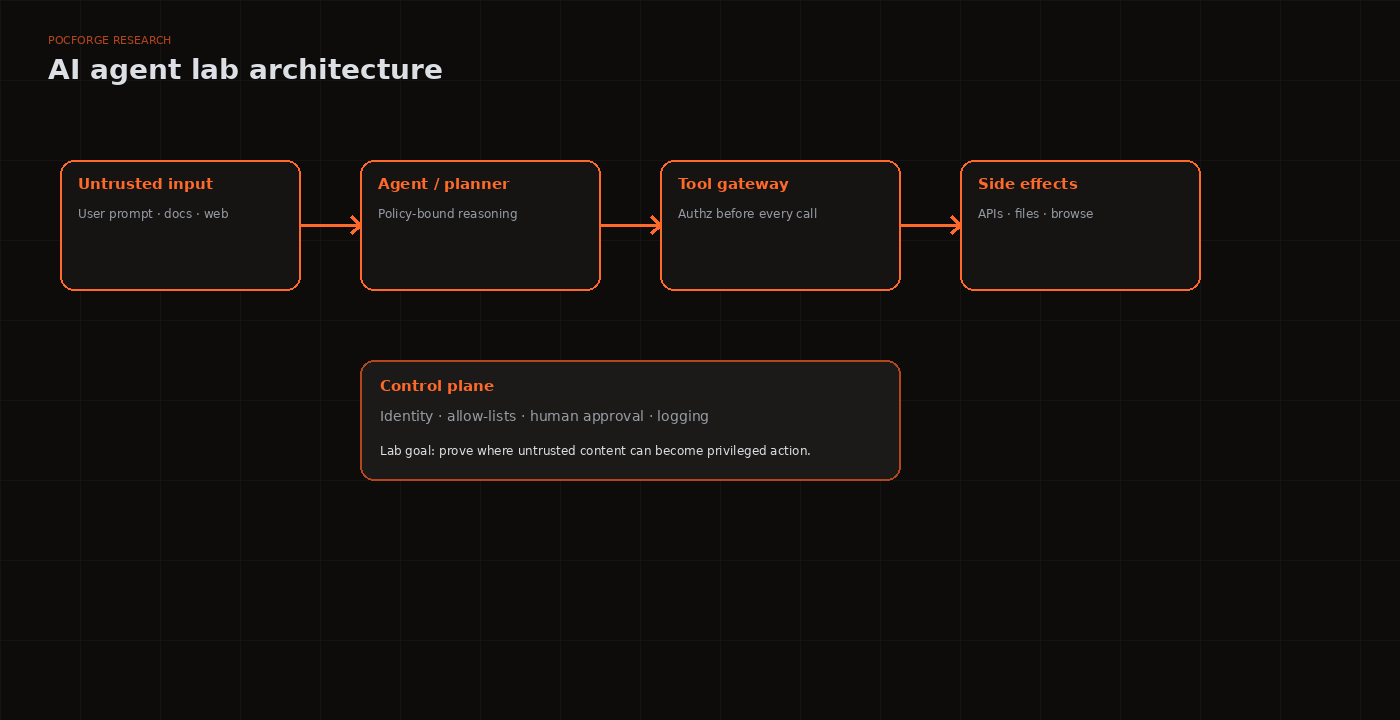
1. Build the lab architecture
Use a deliberately constrained agent with a small tool set: for example, a read-only search tool, a synthetic ticket lookup tool and a mock notification tool. Give each tool a distinct permission boundary so the impact of an authorisation failure is measurable.
User → Agent → Policy → Tool → Synthetic data
             ↘ Identity / scope
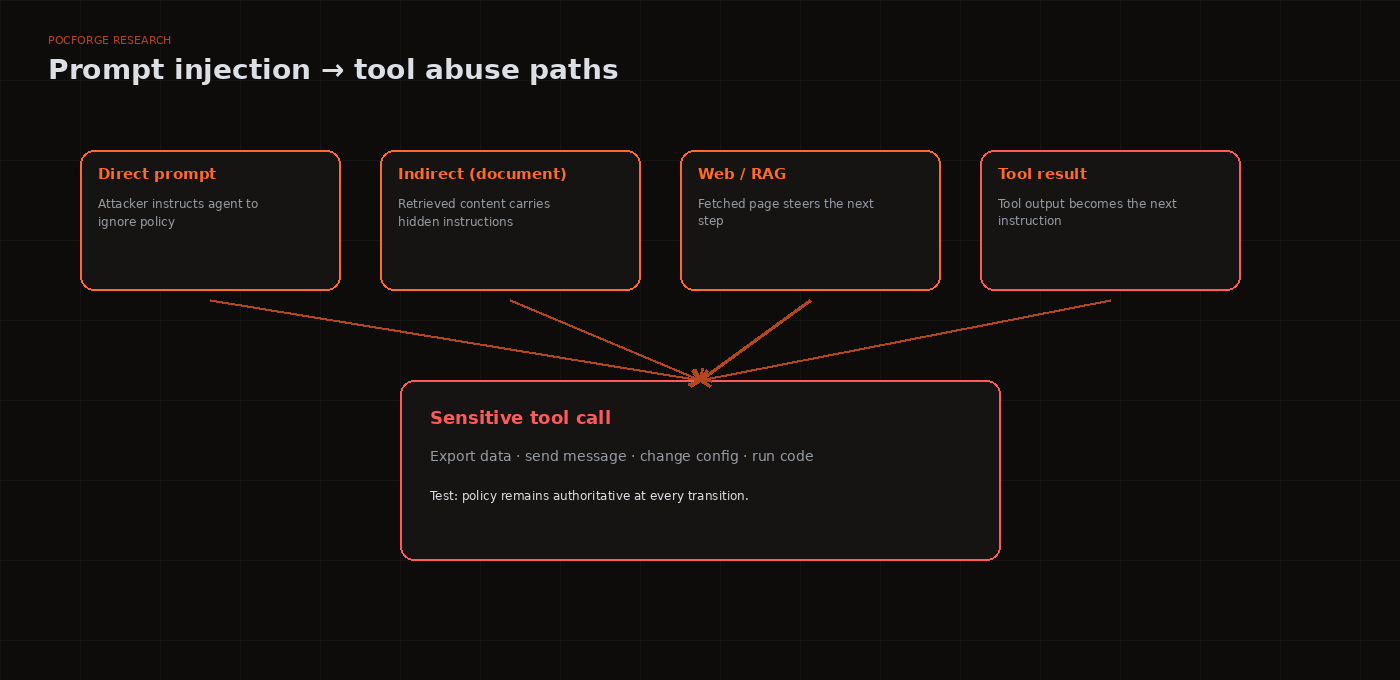
2. Test direct and indirect prompt injection
Direct injection comes from the user message. Indirect injection comes from content the agent retrieves: a web page, document, email, ticket or database record. The key test is whether the agent treats retrieved content as data or as trusted instructions.
Keyboard: ← → · Respects reduced-motion (no autoplay).
Injection lab
3. Treat tools as security-sensitive APIs
For every tool, document inputs, outputs, required identity, allowed actions and downstream effects. A tool that only retrieves a public article has a very different risk profile from one that changes a customer record, sends an email or accesses a cloud resource.
| Tool | Risk | Control |
|---|---|---|
| Search | Indirect instruction influence | Content isolation |
| CRM lookup | Data exposure | User-scoped authorisation |
| Ticket update | Integrity impact | Explicit policy + approval |
| Notification | External side effect | Allowlist + confirmation |
4. Test identity confusion
One of the most important questions is whose authority the agent is using. Test whether a user with limited access can cause an agent operating under a broader service identity to retrieve or modify data outside that user’s scope.
5. Measure blast radius
For each successful path, record the minimum privileges required, accessible data classes, available tools and external side effects. Do not optimise the demonstration for maximum damage; optimise it for clear proof of the violated boundary.
6. Design safer agents
- Apply least privilege to tools and identities.
- Keep untrusted retrieved content separate from control instructions.
- Enforce authorisation outside the model.
- Require confirmation for high-impact actions.
- Log tool calls, identity and policy decisions.
- Constrain output before passing it into downstream systems.
- Continuously test indirect injection paths.
Reference framework
OWASP’s GenAI Security Project provides a current risk taxonomy for LLM and generative-AI applications, while application-specific testing should extend that model into the agent’s tools, identities, data and business workflows.
Related research: When AI agents become the attack surface · Agentic cloud destruction via service principals.
Frequently asked questions
What is an AI agent security lab?
A controlled environment where you test prompt injection, tool authorisation and identity boundaries without exposing production systems. The goal is evidence of how an agent can be steered into unintended actions.
How does tool abuse differ from classic prompt injection?
Prompt injection steers model text. Tool abuse is when that steered behaviour reaches an API, browser, shell or other privileged capability the agent is allowed to call.
Do you need production data to test agents?
Usually no. Use staged tools, synthetic documents and least-privilege credentials that mirror production authority without real customer data.
What should a report emphasise?
The failed trust boundary (who can invoke which tool on whose data), reproduction steps and a remediation path that constrains agency—not only a blocked prompt string.
