
AI and LLM security testing
Human-led testing of applications and agents that call a model: prompt and tool abuse, data leaving the boundary, and authorisation on the software around the model. Not a jailbreak demo and not a regulator product.
- Human-led
- Every reported finding reproduced
- Retest included
-
Human testers leadTooling widens coverage only
-
Scoped firstScope and rules agreed before testing
-
Retest includedIn-scope fixes retested
-
Reproduced findingsEvidence a developer can replay
What we test
Prompt and content abuse
Details
Instructions that try to override the application’s rules, including content hidden in documents the product asks the model to read.
Tool and agent abuse
Details
Actions the agent can take — email, tickets, code, payments, files — and whether a user can aim those tools at someone else’s data.
Authorisation around the model
The API and tenancy in front of the assistant.
Details
The API and tenancy in front of the assistant. A brilliant prompt that an anonymous user cannot send is a different finding from one any customer can send.
Data leaving the boundary
Details
Training-adjacent data, other tenants, system prompts and secrets that come back in a reply or a tool call. We use fixtures, not your production crown jewels, unless you explicitly accept that risk.
Excessive agency
Where the product acts without a person confirming a sensitive step.
Details
Where the product acts without a person confirming a sensitive step. The finding is the missing check, demonstrated safely.
Integrations
Retrieval stores, plugins, browsers and internal APIs the model can reach.
Details
Retrieval stores, plugins, browsers and internal APIs the model can reach. Each integration is named in the scope.
What we will not pretend
Details
We do not certify a model, fine-tune weights, or sell an “AI-resilient” badge for a regulator. Limits are stated in the report.
The ordinary app bugs
Authentication and object access on the product still count.
Details
Authentication and object access on the product still count. An AI feature does not retire API testing.
About this scope
The model is not the whole system. Most serious failures are in the application that wraps it: which tools it may call, whose data it can see, and what a user can make it do. We test that system with fixtures you can afford to leak in a lab.
Not a jailbreak competition
Read more
A screenshot of a model saying something rude is rarely what your customers or your auditors can use. We care when a user reaches another tenant’s documents, triggers a tool the role should not have, or extracts data the product promised to hold. That is application security with a model in the path. Longer notes: agentic AI security.
If the question is only whether the foundation model can be talked into a policy slip in a chat box with no tools and no data, say so. That is a smaller scope, and we will not dress it up as a full product test.
Deliverables
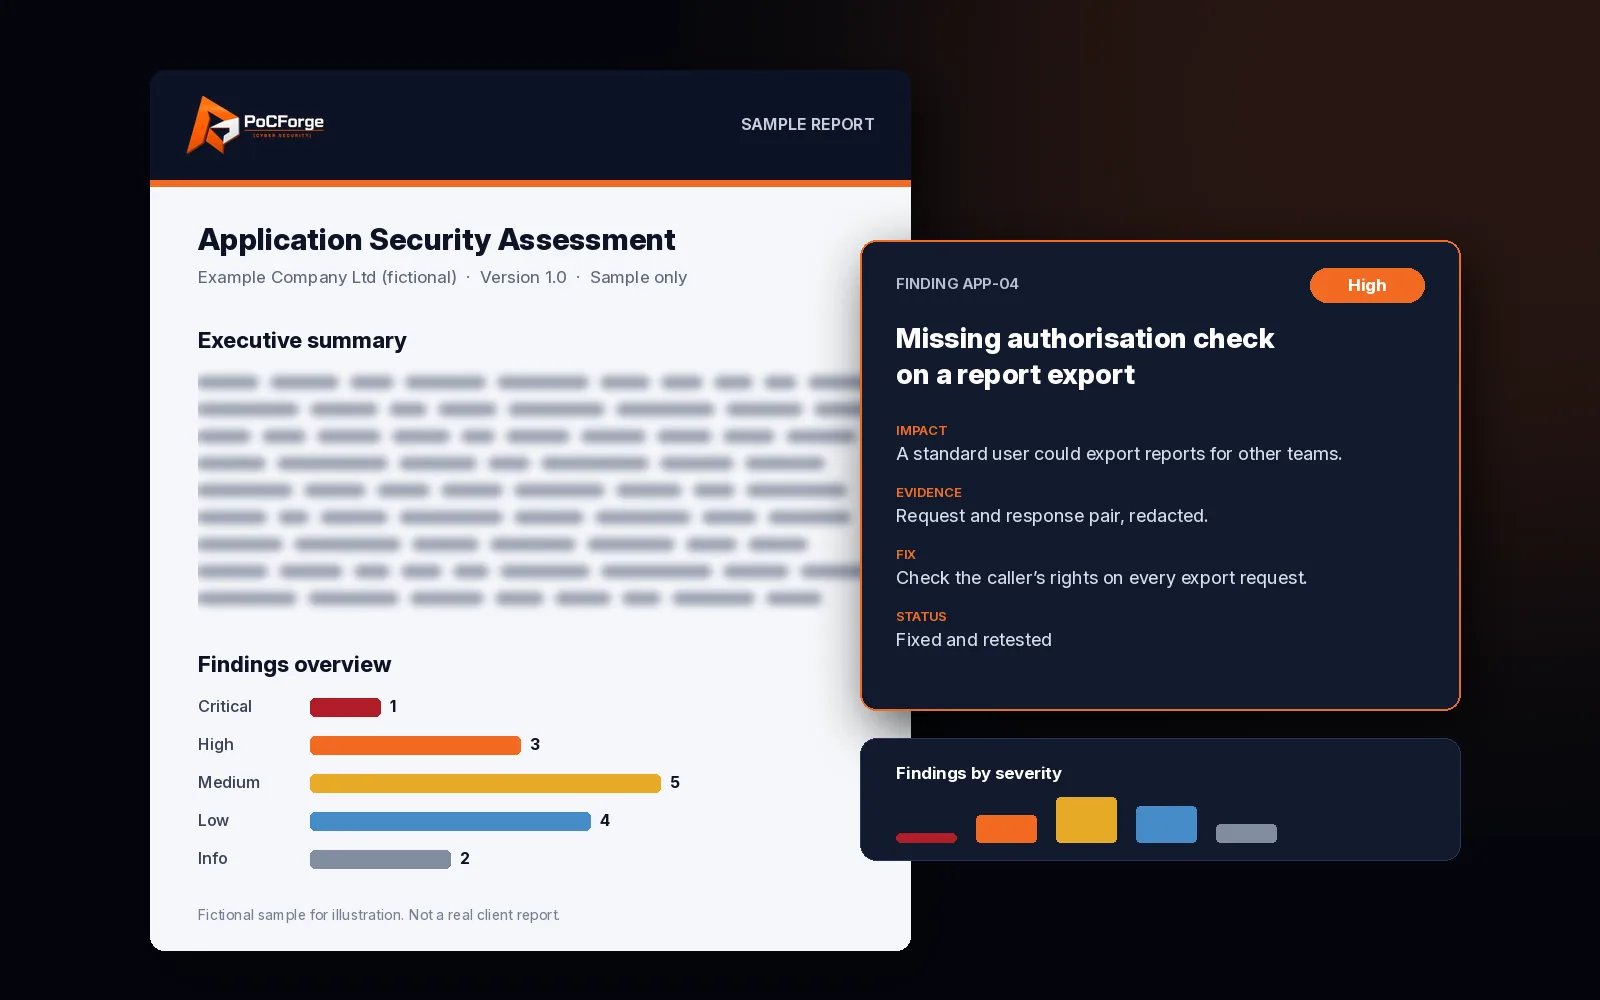
- Executive summary a product owner can read without a research paper attached.
- Findings that name the tool, the data and the role.
- Explicit limits: what was fixture-only, what was out of scope, what a test cannot prove about a future model change.
- Retest notes.
More about the report
A report can support SOC 2 and ISO 27001 evidence. It does not certify the company, and it does not replace the auditor. PoCForge is not a certification body and does not claim CERT-In empanelment. If a contract names an empanelled auditor, read when CERT-In empanelment is required and check the official list before you shortlist.
Who this fits
A good fit
- Teams shipping an assistant, a copilot or an agent inside a product, especially where the model can see customer data or call an internal tool.
- It is a weak fit for a pure model-benchmarking exercise or for anyone who wants a letter that “the AI is safe”.
- Pair it with API testing when the assistant is one client of a broader API.
Investment
Indicative $5,000 – $9,000 before taxes. Price depends on tool count, data sensitivity and how many roles can drive the agent. A chat box with no tools is the low end. An agent that sends mail and reads a tenant store is not. Starting prices · India AI page.
TYPICAL INVESTMENT: $5K – $9K · taxes as applicable · final quote based on tools, data and integrations.
Scope and rules
- System and fixtures. Which assistant, which tools, which data may be used, and a non-production tenant with records we are allowed to see.
- Rules. No testing against production customer data unless you accept it in writing. No attempts to attack the model vendor’s platform.
- Map agency. Tools, retrieval sources, roles and the human confirmation points the product claims to have.
- Test for cross-boundary impact. Prompt and tool abuse aimed at data and actions. Authorisation bugs logged as authorisation bugs.
- Report. What a role could make the system do, with the fixture used, and what we could not test.
- Retest. The same scenarios against the build you fix, inside the window.
Architecture security assessment
Anonymised architecture security assessment pattern for HealthTech / multi-tenant SaaS: trust boundaries, data flows and buyer lessons.
Read the case study →- Human-led
- Every reported finding reproduced
- Retest included
Related
Frequently asked questions
Do you test prompt injection?
Yes, as a means. The finding we stand behind is impact: data, tools or authorisation. A rude reply with no security impact is not dressed up as a critical issue.
Can you test agents and tool use?
Yes. Tools and the permissions around them are the centre of the engagement when the product has them.
Do you review model weights or fine-tunes?
Not as a default. This is a test of the application and its integrations. Weight review is a different piece of work and is not implied.
Should we still test the API?
Yes, if the product has an API that is not only the assistant. AI testing does not replace authorisation testing on the rest of the system.
Do you claim CERT-In empanelment?
No. PoCForge does not claim CERT-In empanelment, and this test is not an AI compliance certificate.
Scope an AI or agent assessment
Describe the assistant, the tools it can call, and the data it is allowed to see in a test tenant.
Request a free scope review →